• OpenAI scientist Noam Brown: The true upper limit of AI may not be able to measure

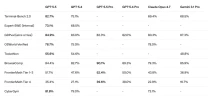
    As large language models gradually tackle complex tasks such as reasoning, automated research, and cybersecurity, traditional methods of evaluating models are facing new challenges.For a long time, the release of models has been accompanied by a report of results consisting of various benchmark tests in areas such as mathematics, programming, scientific question answering, network security, and knowledge reasoning, which are then compared horizontally with the previous generation of models.
    OpenAI scientist Noam Brown: The true upper limit of AI may not be able to measure
  • Claude secretly becomes stupid while doing AI research, and Anthropic is besieged by the research community

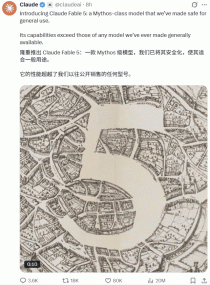
    Claude Fable 5 is the main focus in the AI field today; this “mythical” model performs exceptionally well and has attracted tremendous attention.Andrej Karpathy described it as “very exciting” and an “evolutionary step that deserves a major version upgrade,” on par with the improvements brought by Claude 4.5 last November. In the SWE-bench Pro programming benchmark, Fable 5 achieved a score of 80.3%, which is 11 percentage points higher than Opus 4.8. With a Ruby codebase consisting of 50 million lines of code, Fable 5 completed the entire codebase migration in just one day; if the same task were assigned to a human team, it would take more than two months.

    Claude secretly becomes stupid while doing AI research, and Anthropic is besieged by the research community
  • GPT-5.6 The first batch of actual measurements are here! Precise sniper on Mythos

    Just now, Anthropic released its “big killer” – a product that has been in development for two months.Claude Fable 5andMythos 5It's like dropping a bomb.Apply direct pressure on OpenAI now.

    GPT-5.6 The first batch of actual measurements are here! Precise sniper on Mythos
  • Claude Fable 5 prompt word leaked and the effect was measured in 6 hours. Is it crazy?

    Fable 5 has just been launched, and the system prompts have been leaked:After looking at these prompts, there are a few key points to note:First, Fable has added a persistent storage API (window.storage) for Artifacts. Artifacts are the unique content generated by Claude's code, such as HTML pages and React components. Previously, Artifact data could not be saved and was more like a one-time demo. Now, the data can be saved across sessions, enabling the creation of "memory-based" tools such as leaderboards, time trackers, and diaries.

    Claude Fable 5 prompt word leaked and the effect was measured in 6 hours. Is it crazy?
  • The rapidly heating Voice AI competition has seen the emergence of a startup team called Hojo.

    Voice AI represents another narrative that unfolds alongside the development of general large models. While everyone is focused on the general large models, the relatively quieter field of Voice AI is also seeing the emergence of some noteworthy new models. The keyboard is starting to lose its “dominant position.” Over the past two years, OpenAI introduced the Realtime API, Google launched Gemini Live, and domestic large-model companies have almost all begun to invest in Voice AI. More and more people believe that once agents truly integrate into workflows, voice will become a more natural way to interact with systems than using a keyboard. For an agent to truly become part of a workflow, it must first learn to understand human speech. The foundational capability for this is ASR (Automatic Speech Recognition). The most commonly used benchmark for measuring ASR performance is Hugging Face’s Open ASR Leaderboard, which uses the Word Error Rate (WER) as a key indicator. The lower the WER, the more accurate the recognition.

No More