OpenAI scientist Noam Brown: The true upper limit of AI may not be able to measure
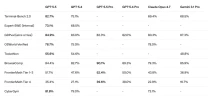
As large language models gradually tackle complex tasks such as reasoning, automated research, and cybersecurity, traditional methods of evaluating models are facing new challenges.For a long time, the release of models has been accompanied by a report of results consisting of various benchmark tests in areas such as mathematics, programming, scientific question answering, network security, and knowledge reasoning, which are then compared horizontally with the previous generation of models.